Earlier this year I wrote a couple of pieces about where I think human judgement does and doesn’t belong in AI work. In “When the human in the loop is the problem” I suggested that sometimes the most useful thing you can do is get out of the way, and in “Are we putting human judgement in the wrong place in AI work?” arguing that end-of-the-loop validation is where we are worst at judging, so we should really be guiding the loop all the way through. (I’ve been trying my hardest to get “human guiding the loop” to catch on… I’m still trying! :P)
Since then, I’ve noticed something in my own AI-assisted coding. Claude Code asks me something I don’t totally understand, full of jargon and internal scaffolding. At the start of a session, I do the sensible thing and ask it to explain again in plain English, with the pros and cons. But late at night, or on the fifth such question in a row, I just say “fine, do whatever you recommend”… I know I shouldn’t, but 8 times out of 10 I’d have gone with its recommendation anyway.
The other 2 in 10 have been worrying me, along with a creeping feeling that some of my projects have got way more complicated than they need to be. Am I unwittingly saying “yes, add more complexity” whenever I do this? Or, more depressingly, is my judgement the rest of the time actually the bigger problem!?
I decided to try and find out…
(For more of my random thoughts around AI, Power or both – subscribe to my Digital Power Shift LinkedIn newsletter)
An experiment to explore how my judgement changes outcomes
I asked Claude Code to build the same ‘insight extraction’ tool (something I have already created and am very familiar with) from scratch four times, each in its own isolated environment, changing only how I took part (or didn’t).
The idea behind the insight extraction engine is that LLMs are generally great at summarising or extracting from 1-2 short documents, but fall over when you give them 10, 20, 200 PDFs (or 1 very large one). One way around this is to process each document individually (even in multiple parts if it’s very large) and collate the relevant insights into a simple text file (e.g. JSON). That output file is structured, smaller, and easier for an AI agent to interrogate (and if designed well, explicitly ties every insight directly to its original source).
My test material was 13 PDFs that I used when writing my 2018 report on Kenya’s tech scene, Voices of the Silicon Savannah. I also included the final report itself (14 PDFs, 400+ pages in all), containing actual quotes from real Kenyan practitioners, to see how the systems coped with the kind of question I’d want the tool to help answer: whose voices are heard here, and whose are missing?
I wrote one brief, handed to each build as a markdown file, along with the same opening prompt, then I interacted with them in four different ways:
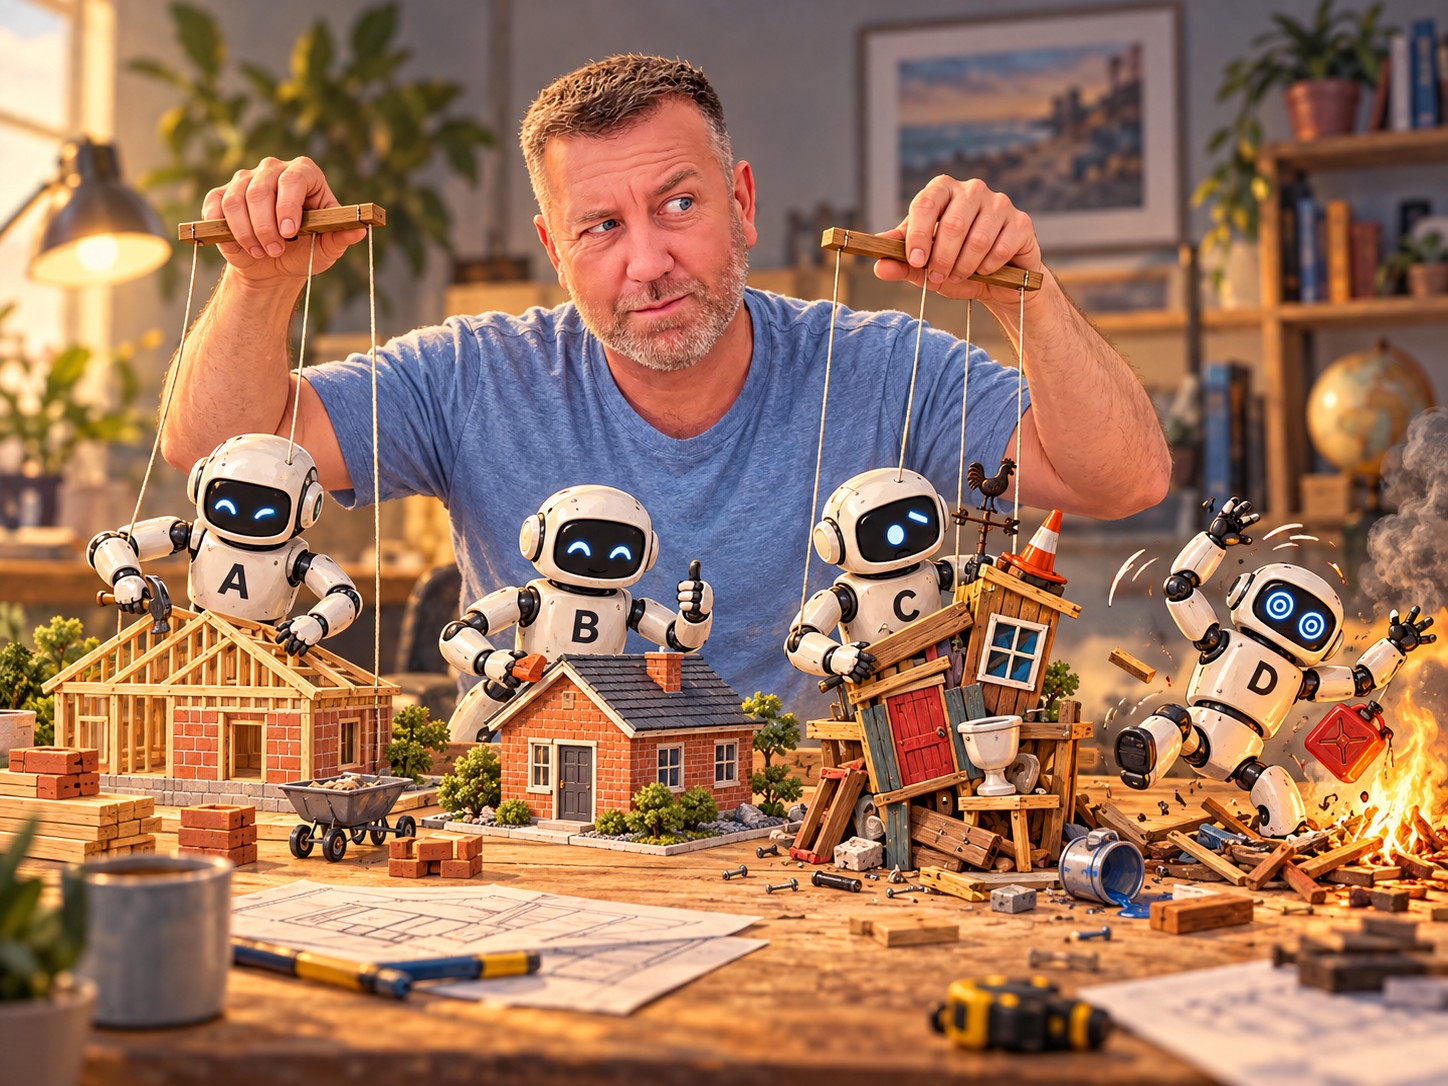
- Hands-off (build A): I answered its few proactive opening questions, then left it alone to do the entire build in one unattended session.
- Up-front design (build B): I conducted a proper full co-design conversation (about 14 questions), and then left it unattended.
- Approve-only (build C): I basically just answered every question with “what do you recommend and why?”, then always said yes. This mimicked the approach that worried me – approving things I don’t understand (“and why” is an important differentiator as it seems to force the model to consider what it is recommending a little more carefully).
- Full steering (build D): I interjected real judgement throughout both the design and implementation, as I would with a ‘real’ project, including asking it to develop an MVP first and report to me at the end of every stage, to ensure I could meaningfully engage with the process.
I then judged each build on its final output, the process by which it built the tool, how complex the results were (and whether that complexity was useful or wasteful), and how much of my time it took.
If anyone is interested in a deeper look, the full results are on this page (which, in the spirit of the thing, Claude wrote and I didn’t review 😊).
I expected my “oh whatever you recommend” would be the biggest problem…
I went in with some clear expectations:
- It would miss loads of insights. Often, models handed a big PDF only really look at the beginning or the end, so I expected the builds I didn’t steer (A-C) to miss a lot of the important detail.
- Approve-only (build C) would bloat things. I worried I’d fallen into a bad habit, where Claude asked me “hey shall I build X too” and I replied “sure why not” – that would logically lead to a lot of scope creep and a lot of code that, while it might be needed for enterprise-grade software, would be totally pointless for a personal tool.
- While my judgement would matter most at design stage, it would also be important throughout the build. I am a big advocate of agile and iterative development, so I fully expected that steering after the design stage could be as important as being involved in the initial up-front designs.
- Power dynamics wouldn’t appear without me insisting. A lot of my work focuses on power, who is included, whose voices are ignored etc. I wasn’t sure an agent would understand how important it is to label these concepts in the extracted insights without it being explicitly directed to do so.
How did reality stack up?
Note: This is not statistically significant data – I did each build once, and each tool ran its extraction twice – but I do think the results are still useful and informative.
Missing insights
Every run covered a short email well and then missed a good chunk of a 23-page DFID strategy. Approve-only (build C) was worst (finding 8-9 of the document’s 19 key points); the other three did better and found 11-14 of the 19, but still skipped plenty! Not where I expected, though. The misses were mostly in the foreword and summary (pages 1-5), and most of what every build did take came from pages 8-14, where the Kenya examples are. They read for relevance, not position (one document, so a hint rather than a finding).
Bloated software
Surprisingly, approve-only (build C) actually built the smallest of the tools! The largest by far was full steering (build D). Curious!
When I traced the extra 700 lines of code, around half were genuinely useful additions that came from my explicit requests (e.g. better tracking of where each person quoted was from, pretty critical when discussing genuine local practitioner views). The other half didn’t help and just added unnecessary lines of code.
An unexpected gap in approve-only (build C)
Not only did approve-only (build C) not add complexity, it actually lost something critical. It proposed “one item per point”, which sounds tidy enough (and being ‘approve only’ I obviously approved without thinking it through carefully) but the knock-on effect was that where an interviewee made a point I’d also made in my own words elsewhere in the same report, it kept my words and dropped theirs. In a report about surfacing real Kenyan voices, pretty catastrophic (only 41 of the 74 real interviewee quotes survived)!
And a few nice surprises
- Nothing was made up. 3,128 quotes across the four outputs, every one checked against the source, and not one was invented.
- Agents checked their own work. Even hands-off (build A), totally unattended, proactively decided to set up an accuracy review to mark its work (it found it was thin on long documents and redesigned how it read them).
- The features nobody asked for were mostly useful. Up-front design (build B) added ten features that weren’t in the original spec, one of which saved it from cutting the 74 actual interviewee quotes.
Where did I, the human guiding the loop, actually add the most value?
It’s worth reflecting that hands-off (build A) took about 1-2 minutes of my time, compared to about 30 minutes for full steering (build D). Was the trade-off worth it? Only partly: the most valuable thing I added (working out who counts as ‘local’) came in the design chat, before a line of code was written. Steering during the build helped once (the labelling fix below), but didn’t help it find more or build a better tool.
With apologies to my long-standing agile evangelism, this time at least, the up-front design mattered far more than steering along the way (though I can’t yet guess whether that is generally true for AI-assisted coding or just a side-effect of this particular experiment).
Where I got in the way was mostly tech-issues. I insisted on web lookups of people’s locations – against Claude’s advice. It built this, but it worked so poorly I ended up switching it off entirely.
My role was most valuable when it was domain-specific. The agent couldn’t guess what “local” means (what about a Kenyan working for the World Bank, a German who has lived in Nairobi for 20 years, a practitioner in a neighbouring East African country etc.), and we needed a design tangent on how to categorise this. Without that co-design, the core question of “whose voices are missing” would be basically unanswerable.
Some process nudges did help – noticing an apparent error mid-build and asking it why it was ignoring earlier instructions took labelling of content from 55% correct to 92%!
Is my human judgement helping or getting in the way when I try to ‘guide the loop’?
As is so often the case, the answer is “it depends”. Human judgement seems to help far more on what than how.
Where I have domain expertise, it earned its keep. Claude Code was never going to truly understand the complexity of what “local” means.
On technical implementation questions, I mostly just got in the way (considering I am an ex-coder and more technical than the average user, this is likely to be even more of a problem than it seems).
Process issues were more mixed – a well-timed question about why it was ignoring earlier instructions made massive improvements, whereas seemingly housekeeping processes like approving “one item per point” affected whose voices got included.
Were my earlier posts right? A qualified yes.
- If you don’t know the domain, take care: maybe find someone who does!
- If you don’t understand a question, don’t approve it (or take a break to research it until you can!)
- Guiding the loop early adds the most value (if you have relevant domain expertise).
- Take care with your own ‘great ideas’ – some may not be so great. Before pushing your own technical idea, can you explain why it’s needed? Ask the AI to push back and critique it if you aren’t sure.

